Speakers: Dani Roach & Carolyn DeLuca, University of Saint Thomas
We’re all very familiar with print serials cancellation projects, but now we’re starting to see this in the electronic world, particularly as more libraries are walking away from big deals. There are lots of documents talking about the life-cycle of an eresource, but cancellation hasn’t really been addressed until recently, with the TERMS section covering it along with others.
As much work as it is to get into a relationship with a vendor/resource, it’s just has hard to leave it.
Eresource breakups are often caused by the renewal time, low use, high cost, etc. The heart-breaker could be internal players like the liaison or ERMS staff acting as the divorce lawyer once the decision was made, or external players like the publisher/provider/broker/consortium/vendor.
The three types of breakups are cancelled, ceased, or migrated. In each case, you need to assess the status, the holdings, the platform, and the provider. There are some things we have control over, but there are many more things outside of our control, due to the marketplace around information. Don’t take it personally, libraries. It’s not about you.
There are tools where you make the change (catalog, ERM, course management system, and paper files, proxy config, local tools, customized holdings, archives/Portico/local), and then there are tools where you announce the change (LibGuides, RefWorks, site-wide search metadata, blogs & other social media).
UKSG created a cancellation form, which looks lovely. And sadly, our ERMS can’t track everything.
Vendors can play the role of best friend. They want to help, and make sure we’re making the right decision so we don’t come back crying on their shoulder later. Some tips: Know who signed the license, confirm post-cancellation rights, do not count on a refund, plan cancellations and migrations well in advance of renewal, and know what you want (if replacing a product, do your research).
Considerations from the publisher/provider: ownership transfers, licensing, grace periods, overlap periods, and personal relationships.
When does it end? In general, the library gets to decide when to shut it down. It could be immediate, or you could wait until the end of the semester or the end of the subscription term. Sometimes resources are put on probation and given some time to demonstrate value to the community.
What’s left? Post-cancellation access? Deleting or weeding — did you ask the provider to remove the old edition? When a product has migrated, you’ll need to change the tutorials, screenshots, videos, etc.
“Belinha has more than good looks” by Francisco Martins
What the “Google Generation” Says About Using Library & Information Collections, Services, and Systems in the Digital Age
Speaker: Michael Eisenberg, University of Washington Information School
We’ve moved from scarcity to abundance to overload. We have so many great resources our students don’t know where to begin. They’re overwhelmed.
Think about how our computing technology has evolved and shrank in both size and price while increasing in power over the past 30 years. Where will be 20 years from now?
We live in a parallel information universe that is constantly feeding information back to us. The library is anywhere anytime, so how can we best meet the information needs of our users?
Project Information Literacy seeks to answer what it means to be a student in the digital age. They have been assessing different types of students on how they find and use information to get generalized pictures of who they are.
Why, when you have an information need, do you turn to Google first and not research databases?
Students ignore faculty warnings about Wikipedia. They still use it, but they just don’t cite it.
Students aren’t really procrastinators, they’re just busy. They are working to the last minute because every minute is highly scheduled. Have we changed our staffing or the nature of our services to help them at point of need?
Students don’t think of librarians as people who can help them with their research, they think of them as people who can help them with resources. They are more likely to go to their instructors and classmates before librarians during the research process. The hardest part for them is getting started and defining the topic (and narrowing it down). They don’t think librarians can help them with that, even though we can, and do (or should if we aren’t already).
Students are more practiced at writing techniques than research strategies. Professors complain that students can’t write, but maybe writing shouldn’t be the only method of expression.
Most students don’t fully understand the research process and what is expected. They need clarity on the nature and scope of assignments, and they aren’t used to critical thinking (“just tell me what you want and I’ll give it to you”). Most handouts from profs don’t explain this well, focusing more on mechanics and sending students to the library shelves (and not to databases or online resources). Rarely do they suggest talking to the librarian.
Students are not the multi-taskers we think they are, particularly during crunch time. Often they will use the library and library computers to force themselves to limit the distractions and focus. They use Facebook breaks as incentives to get things done.
After they graduate, former students are good with technology, but not so good with low-tech, traditional research/information discovery skills.
Information literacy needs are more important than ever, but they are evolving. Search to task to use to synthesis to evaluation — students need to be good at every stage. The library is shifting from the role of information to space, place, and equipment. Buying the resources is less of an emphasis (although not less in importance), and the needs change with the academic calendar.
What do we do about all this?
Infuse high quality, credible resources and materials into courses and classes. Consider resources and collections in relation to Wikipedia. Infuse information literacy learning opportunities into resources, access systems, facilities, and services (call it “giving credit,” which they understand more than citing). Provide resources, expertise, and services related to assignments. Re-purpose staff and facilities related to calendar and needs. Offer to work with faculty to revise handouts — emphasize the quality of resources not the mechanics. Offer flexible and collaborative spaces with a range of capabilities and technology, less emphasis on print collection development. Consider school-to-work transitions in access systems, resources, services, and instruction.
Beyond formal instruction, what are the ways we can help students gain the essential information literacy skills they need? That is the challenge for eresources librarians.
Speaker: Susan Stearns, VP of Strategic Partnerships of Ex Libris Group
Both library as a percentage of university expenditures and the number of library staff per student have been going down. The percentage of library expenditures spent on electronic resources has been going up dramatically.
There is a need to eliminate the duplication of data and workflows, and the silo systems in libraries today. Alma intends to unify both the data and the data environment: acquisitions, metadata management, fulfillment, and analytics.
Collaborative metadata management is a hybrid model to balance global sharing with local needs. In English, this means you can have a catalog that includes both an inventory of locally owned items and a collection of items shared by one or more “communities.” Multiple metadata schema are supported within the system in their native formats — no crosswalks required.
Individual library staff users can set up “home pages” within the system that includes widgets with data, alerts, and reports. This can help with making decisions about the collection. Analytics are also embedded directly in the workflow (i.e. a graph representing the balance remaining in a fund displayed when an order using that fund is viewed/entered).
Speaker: Maria Bunevski, Ex Libris
Preparation for moving to a new system, particularly a radically new system like Alma, requires spending some time thinking about workflows, data, technical aspects (integration points, etc.), and training.
Project initiation phase requires a lot of training sessions to fully grasp all of the change that needs to happen.
The implementation phase involves a mix of on-site work and remote tweaking. At some point work has to freeze in the old system before cutting over to the new one.
VCU is currently in the post-implementation phase. This is the point where un-configured things are discovered, along with gaps in workflow.
Speaker: John Duke, VCU Libraries
They had Aleph, SFX, Verde, MetaLib, Primo, ARC, ILLiad, university systems, etc. before, and they wanted to bring the functions together. They didn’t end up with a monolithic system for everything, but they got closer.
Workflows and other aspects have been simplified.
The system is not complete, either because Ex Libris hadn’t thought of it or because VCU hasn’t figured out how to incorporate it. Internet outages, security issues, and conceptual difficulties have thrown up road blocks along the way.
“Educational Utility Computing: Perspectives on .edu and the Cloud”
Mark Ryland, Chief Solutions Architect at Amazon Web Services
AWS has been a part of revolutionizing the start-up industries (i.e. Instagram, Pinterest) because they don’t have the cost of building server infrastructures in-house. Cloud computing in the AWS sense is utility computing — pay for what you use, easy to scale up and down, and local control of how your products work. In the traditional world, you have to pay for the capacity to meet your peak demand, but in the cloud computing world, you can level up and down based on what is needed at that moment.
Economies, efficiencies of scale in many ways. Some obvious: storage, computing, and networking equipment supply change; internet connectivity and electric power; and data center sitting, redundancy, etc. Less obvious: security and compliance best practices; datacenter internal innovations in networking, power, etc.
AWS and .EDU: EdX, Coursera, Texas Digital Library, Berkeley AMP Lab, Harvard Medical, University of Phoenix, and an increasing number of university/school public-facing websites.
Expects that we are heading toward cloud computing utilities to function much like the electric grid — just plug in and use it.
“Libraries in Transition”
Marshall Breeding, library systems expert
We’ve already seen the shift of print to electronic in academic journals, and we’re heading that way with books. Our users are changing in the way they expect interactions with libraries to be, and the library as space is evolving to meet that, along with library systems.
Web-based computing is better than client/server computing. We expect social computing to be integrated into the core infrastructure of a service, rather than add-ons and afterthoughts. Systems need to be flexible for all kinds of devices, not just particular types of desktops. Metadata needs to evolve from record-by-record creation to bulk management wherever possible. MARC is going to die, and die soon.
How are we going to help our researchers manage data? We need the infrastructure to help us with that as well. Semantic web — what systems will support it?
Cooperation and consolidation of library consortia; state-wide implementations of SaaS library systems. Our current legacy ILS are holding libraries back from being able to move forward and provide the services our users want and need.
A true cloud computing system comes with web-based interfaces, externally hosted, subscription OR utility pricing, highly abstracted computing model, provisioned on demand, scaled according to variable needs, elastic.
“Moving Up to the Cloud”
Mark Triest, President of Ex Libris North America
Currently, libraries are working with several different systems (ILS, ERMS, DRs, etc.), duplicating data and workflows, and not always very accurately or efficiently, but it was the only solution for handling different kinds of data and needs. Ex Libris started in 2007 to change this, beginning with conversations with librarians. Their solution is a single system with unified data and workflows.
They are working to lower the total cost of ownership by reducing IT needs, minimize administration time, and add new services to increase productivity. Right now there are 120+ institutions world-wide who are in the process of or have gone live with Alma.
Automated workflows allow staff to focus on the exceptions and reduce the steps involved.
Descriptive analytics are built into the system, with plans for predictive analytics to be incorporated in the future.
Future: collaborative collection development tools, like joint licensing and consortial ebook programs; infrastructure for ad-hoc collaboration
“Cloud Computing and Academic Libraries: Promise and Risk”
John Ulmschneider, Dean of Libraries at VCU
When they first looked at Alma, they had two motivations and two concerns. They were not planning or thinking about it until they were approached to join the early adopters. All academic libraries today are seeking to discover and exploit new efficiencies. The growth of cloud-resident systems and data requires academic libraries to reinvigorate their focus on core mission. Cloud-resident systems are creating massive change throughout out institutions. Managing and exploiting pervasive change is a serious challenge. Also, we need to deal with security and durability of data.
Cloud solutions shift resources from supporting infrastructure to supporting innovation.
Efficiencies are not just nice things, they are absolutely necessary for academic libraries. We are obligated to upend long-held practice, if in doing so we gain assets for practice essential to our mission. We must focus recovered assets on the core library mission.
Agility is the new stability.
Libraries must push technology forward in areas that advance their core mission. Infuse technology evolution for libraries with the values needs of libraries. Libraries must invest assets as developers, development partners, and early adopters. Insist on discovery and management tools that are agnostic regarding data sources.
Managing the change process is daunting.. but we’re already well down the road. It’s not entirely new, but it does involve a change in culture to create a pervasive institutional agility for all staff.
Updates from Serials Solutions – mostly Resource Manager (Ashley Bass):
Keep up to date with ongoing enhancements for management tools (quarterly releases) by following answer #422 in the Support Center, and via training/overview webinars.
Populating and maintaining the ERM can be challenging, so they focused a lot of work this year on that process: license template library, license upload tool, data population service, SUSHI, offline date and status editor enhancements (new data elements for sort & filter, new logic, new selection elements, notes), and expanded and additional fields.
Workflow, communication, and decision support enhancements: in context help linking, contact tool filters, navigation, new Counter reports, more information about vendors, Counter summary page, etc. Her most favorite new feature is “deep linking” functionality (aka persistent links to records in SerSol). [I didn’t realize that wasn’t there before — been doing this for my own purposes for a while.]
Next up (in two weeks, 4th quarter release): new alerts, resource renewals feature (reports! and checklist!, will inherit from Admin data), Client Center navigation improvements (i.e. keyword searching for databases, system performance optimization), new license fields (images, public performance rights, training materials rights) & a few more, Counter updates, SUSHI updates (making customizations to deal with vendors who aren’t strictly following the standard), gathering stats for Springer (YTD won’t be available after Nov 30 — up to Sept avail now), and online DRS form enhancements.
In the future: license API (could allow libraries to create a different user interface), contact tools improvements, interoperability documentation, new BI tools and reporting functionality, and improving the Client Center.
Also, building a new KB (2014 release) and a web-scale management solution (Intota, also coming 2014). They are looking to have more internal efficiencies by rebuilding the KB, and it will include information from Ulrich’s, new content types metadata (e.g. A/V), metadata standardization, industry data, etc.
Summon Updates (Andrew Nagy):
I know very little about Summon functionality, so just listened to this one and didn’t take notes. Take-away: if you haven’t looked at Summon in a while, it would be worth giving it another go.
360 Link Customization via JavaScript and CSS (Liz Jacobson & Terry Brady, Georgetown University):
Goal #1: Allow users to easily link to full-text resources. Solution: Go beyond the out-of-the box 360 Link display.
Goal #2: Allow users to report problems or contact library staff at the point of failure. Solution: eresources problem report form
They created the eresources problem report form using Drupal. The fields include contact information, description of the resource, description of the problem, and the ability to attach a screenshot.
When they evaluated the slightly customized out of the box 360 Link page, they determined that it was confusing to users, with too many options and confusing links. So, they took some inspiration from other libraries (Matthew Reidsma’s GVUS jQuery code available on Github) and developed a prototype that uses custom JavaScript and CSS to walk the user through the process.
Some enhancements included: making the links for full-text (article & journal) butttons, hiding additional help information and giving some hover-over information, parsing the citation into the problem report page, and moving the citation below the links to full-text. For journal citations with no full-text, they made the links to the catalog search large buttons with more text detail in them.
Some of the challenges of implementing these changes is the lack of a test environment because of the limited preview capablities in 360 Link. Any changes actually made required an overnight refresh and they would be live, opening the risk of 24 hour windows of broken resource links. So, they created their own test environment by modifying test scenarios into static HTML files and wrapping them in their own custom PHP to mimic the live pages without having to work with the live pages.
[At this point, it got really techy and lost me. Contact the presenters for details if you’re interested. They’re looking to go live with this as soon as they figure out a low-use time that will have minimal impact on their users.]
Customizing 360 Link menu with jQuery (Laura Wrubel, George Washington University)
They wanted to give better visual clues for users, emphasize the full-text, have more local control over linkns, and visual integration with other library tools so it’s more seamless for users.
They started with Reidsma’s code, then then forked off from it. They added a problem link to a Google form, fixed ebook chapter links and citation formatting, created conditional links to the catalog, and linked to their other library’s link resolver.
They hope to continue to tweak the language on the page, particularly for ILL suggestion. The coverage date is currently hidden behind the details link, which is fine most of the time, but sometimes that needs to be displayed. They also plan to load the print holdings coverage dates to eliminate confusion about what the library actually has.
In the future, they would rather use the API and blend the link resolver functionality with catalog tools.
Custom document delivery services using 360 Link API (Kathy Kilduff, WRLC)
They facilitate inter-consortial loans (Consortium Loan Service), and originally requests were only done through the catalog. When they started using SFX, they added a link there, too. Now that they have 360 Link, they still have a link there, but now the request form is prepopulated with all of the citation information. In the background, they are using the API to gather the citation information, as well as checking to see if there are terms of use, and then checking to see if there are ILL permissions listed. They provide a link to the full-text in the staff client developed for the CLS if the terms of use allow for ILL of the electronic copy. If there isn’t a copy available in WRLC, they forward the citation information to the user’s library’s ILL form.
License information for course reserves for faculty (Shanyun Zhang, Catholic University)
Included course reserve in the license information, but then it became an issue to convey that information to the faculty who were used to negotiating it with publishers directly. Most faculty prefer to use Blackboard for course readings, and handle it themselves. But, they need to figure out how to incorporate the library in the workflow. Looking for suggestions from the group.
Advanced Usage Tracking in Summon with Google Anaytics (Kun Lin, Catholic University)
In order to tweak user experience, you need to know who, what, when, how, and most important, what were they thinking. Google Anayltics can help figure those things out in Summon. Parameters are easy ways to track facets, and you can use the data from Google Analytics to figure out the story based on that. Tracking things the “hard way,” you can use the conversion/goal function of Google Analytics. But, you’ll need to know a little about coding to make it work, because you have to add some javascripts to your Summon pages.
Use of ERM/KB for collection analysis (Mitzi Cole, NASA Goddard Library)
Used the overlap analysis to compare print holdings with electronic and downloaded the report. The partial overlap can actually be a full overlap if the coverage dates aren’t formatted the same, but otherwise it’s a decent report. She incorporated license data from Resource Manager and print collection usage pulled from her ILS. This allowed her to create a decision tool (spreadsheet), and denoted the print usage in 5 year increments, eliminating previous 5 years use with each increment (this showed a drop in use over time for titles of concern).
Discussion of KnowledgeWorks Management/Metadata (Ben Johnson, Lead Metadata Librarian, SerialsSolutions)
After they get the data from the provider or it is made available to them, they have a system to automatically process the data so it fits their specifications, and then it is integrated into the KB.
They deal with a lot of bad data. 90% of databases change every month. Publishers have their own editorial policies that display the data in certain ways (e.g., title lists) and deliver inconsistent, and often erroneous, metadata. The KB team tries to catch everything, but some things still slip through. Throught the data ingestion process, they apply rules based on past experience with the data source. After that, the data is normalized so that various title/ISSN/ISBN combinations can be associated with the authority record. Finally, the data is incorporated into the KB.
Authority rules are used to correct errors and inconsistencies. Rule automatically and consistently correct holdings, and they are often used to correct vendor reporting problems. Rules are condified for provider and database, with 76,000+ applied to thousands of databases, and 200+ new rules are added each month.
Why does it take two months for KB data to be corrected when I report it? Usually it’s because they are working with the data providers, and some respond more quickly than others. They are hoping that being involved with various initiatives like KBART will help fix data from the provider so they don’t have to worry about correcting it for us, but also making it easier to make those corrections by using standards.
Client Center ISSN/ISBN doesn’t always work in 360 Links, which may have something to do with the authority record, but it’s unclear. It’s possible that there are some data in the Client Center that haven’t been normalized, and could cause this disconnect. And sometimes the provider doesn’t send both print and electronic ISSN/ISBN.
What is the source for authority records for ISSN/ISBN? LC, Bowker, ISSN.org, but he’s not clear. Clarification: Which field in the MARC record is the source for the ISBN? It could be the source of the normalization problem, according to the questioner. Johnson isn’t clear on where it comes from.
I told a friend yesterday that I felt like I didn’t carpe enough diem at Charleston Conference. It was my first time attending, and I didn’t have a good sense of the flow. I wasn’t prepared for folks to be leaving so early on Saturday, I didn’t know about the vendor showcase on Wednesday until after I made my travel arrangements, and I felt like I didn’t make the most of the limited time I had.
Next time will be better. And yes, there will be a next time, but maybe after a year or two. I understand from some regulars that the plenary sessions were below average this year, which matched my disappointed expectations. Now knowing that there is little vetting of the concurrent sessions, I will be more particular in my choices the next time, and hopefully select sessions where the content matches my expectations based on the abstracts.
The food in Charleston definitely met my expectations. I had tasty shrimp & grits a couple times, variations on fried chicken nearly every day, and a yummy cup of she crab soup. Tried a few local brews, and a dark & stormy from a cool bar that brews their own ginger beer. I’d go back for the food for sure.
Speakers: Ladd Brown, Andi Ogier, and Annette Bailey, Virginia Tech
Libraries are not about the collections anymore, they’re about space. The library is a place to connect to the university community. We are aggressively de-selecting, buying digital backfiles in the humanities to clear out the print collections.
Guess what? We still have our legacy workflows. They were built for processing physical items. Then eresources came along, and there were two parallel processes. Ebooks have the potential of becoming a third process.
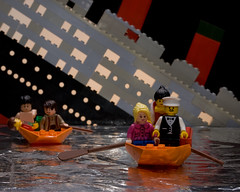
Along with the legacy workflows, they have a new Dean, who is forward thinking. The Dean says it’s time to rip off the bandaid. (Titanic = old workflow; iceberg = eresources; people in life boats = technical resources team) Strategic plans are living documents kept on top of the desk and not in the drawer.
With all of this in mind, acquisitions leaders began meeting daily in a group called Eresources Workflow Weekly Work, planning the changes they needed to make. They did process mapping with sharpies, post-its, and incorporated everyone in the library that had anything to do with eresources. After lots of meetings, position descriptions began to emerge.
Electronic Resource Supervisor is the title of the former book and serials acquisitions heads. The rest — wasn’t clear from the description.
They had a MARC record service for ejournals, but after this reorganization process, they realized they needed the same for ebooks, and could be handled by the same folks.
Two person teams were formed based on who did what in the former parallel processes, and they reconfigured their workspace to make this more functional. The team cubes are together, and they have open collaboration spaces for other groupings.
They shifted focus from maintaining MARC records in their ILS to maintaining accurate title lists and data in their ERMS. They’re letting the data from the ERMS populate the ILS with appropriate MARC records.
They use some Python scripts to help move data from system to system, and more staff are being trained to support it. They’re also using the Google Apps portal for collaborative projects.
They wanted to take risks, make mistakes, fail quickly, but also see successes come quickly. They needed someplace to start, and to avoid reinventing the wheel, so they borrowed heavily from the work done by colleagues at James Madison University. They also hired Carl Grant as a consultant to ask questions and facilitate cross-departmental work.
Big thing to keep in mind: Administration needs to be prepared to allow staff to spend time learning new processes and not keeping up with everything they used to do at the same time. And, as they let go of the work they used to do, please tell them it was important or they won’t adopt the new work.
There are two components — the recommender and hot articles.
This began in 2009 with the article recommended, and as of this year, it’s used by over 1100 institutions. This year they added the hot articles service, with “popularity reports”. And, there is a mobile app for the hot articles service. Behind the scenes, there is the bX Data Lab, where they run experiments and quality control. They’re also interested in data mining researchers who might want to take the data and use it for their own work.
The data for bX comes from SFX users who actively contribute the data from user clicks at their institutions. It’s content-neutral, coming from many institutions.
bX is attempting to add some serendipity to searches that by definition require some knowledge of what you are looking for. When you find something from your searching, the bX recommender will find other relevant articles for you, based on what other people have used in the past. The hot articles component will list the most used articles from the last month that are on the same topic as your search result.
It currently works only with articles, but they are collecting data on ebooks that may eventually lead to the ability to recommend them as well.
The hot articles component is based on HILCC subjects that have been assigned to journal titles, so it’s not as precise as the recommender.
You can choose to limit the recommendations to only your holdings, but that limits the discovery. You can have indicators that show whether the item is available locally or not.
It’s available in SFX, Primo, Scopus, and the Science Direct platform. Hot articles can be embedded in LibGuides.
Atmetrics – probably will be incorporated to enhance the recommender service.
They are looking at article metrics calculated as a percentile rank per topic, which is more relevant today than the citations that may come five years down the road. It’s based on usage through SFX and bX, but not direct links or DOI links.
Speakers: Matt Torrence, Audrey Powers, & Megan Sheffield, University of South Florida
Are collection development policies viable today? In order answer this, they sent out a survey to ARL libraries to see if they are using them or if they’re experimenting with something else. They were also interested to know when and how data is being used in the process.
The survey results will be published in the proceedings. I will note anything here that seems particularly interesting, but it looks like all they are doing now is reading that to us.
Are collection development policies being used? Yes, sort of. Although most libraries in the survey do have them, they tend to be used for accreditation and communication, and often they are not consistently available either publicly or internally.
What are the motivations for using collection development policies? Tends to be more for external/marketing than for internal workflows.
They think that a collection development “philosophy” may be a more holistic response to the changing nature of collection development.
Speakers: two people from the University of Arkansas at Little Rock, but they had four names on the PPT, and I didn’t catch who was who
They recently decided to revise their collection development policy/guidelines based on a recommendation from a strategic planning ARL Collection Analysis Project. They also had quite a few new librarians who needed to work with faculty selectors.
They did a literature review and gathered information on practices from peer institutions. They actually talked to the Office of Institutional Research about data on academic degree programs. And, like students, they looked online to see if they could borrow from existing documents.
One thing they took away from the review of what other libraries have out there was that they needed to have the document live on the web, and not just on paper in a binder in someone’s office.
Policies/guidelines should be continuously updating, flexible, acknowledge consortia memberships, acknowledge new formats, and strike a balance between being overly detailed and too general.
They see that the project has had some benefits, not only to themselves but also to provide a guide for current and future users of the policies. It is also a valuable tool for transmitting institutional memory.
“One size fits all. Welcome to the 80’s” by Stephan van Es
Speaker: Anne McKee, GWLA
SERU was heavily involved in putting this session together. SERU hopes to put away with the madness of licensing and come up with mutually agreeable terms.
Most libraries purchase ebooks in order to make them available 24/7 to their users. While they haven’t grown to proportion sizes larger than print in library collections, they are heading there.
Researchers like ebooks because they don’t have to return them, and are more accessible than print books in the developing world. Students appreciate the ease of accessibility, particularly distance learnings, but given the choice they would take print over e every time. Libraries like them because there are easier/better ways of assessing usage and value to their users, but there are licensing and DRM headaches.
Speaker: Adam Chesler, Business Expert Press / Momentum Press
He has worked for large publishers, but now works for a small, new publisher.
What’s hard for a new publisher to break into the library market? Creating awareness, providing value — acquisition librarians are already overwhelmed with sales pitches via email. Authors may be wary of working with an unknown outlet when there are so many other options. They have to figure out ways to do this creatively.
Gaining budget shares in library materials budgets is challenging, where established publishers have long-standing space. Setting up trials for libraries and following up on them is challenging when one person is responsible for every business/science library in North America. “If you set up a trial, it would be much better to tell me to go to hell than ignore me.”
What’s easy? Nothing.
Well, being an e-only publisher means they don’t have responsibility for a print legacy that needs to be converted to online. That’s easy. They also have more freedom to experiment, particularly with pricing models. And SERU. That’s easy. They also don’t have their own platform, so they make the books available on established providers libraries are already comfortable using.
Speaker: Kimberly Steinle, Duke University Press
When they created the ebook side of the press, they modeled it after the ejournal side, with similar tiered pricing. They also work with the other ebook platforms and their pricing and licensing models.
While the ejournal collection sales are significant, they were surprised to find that ebook collections were not as popular as individual title sales.
They thought selling ebooks would be easy, since they already had existing relationships. MARC records, pricing, technology — not as easy as they thought. Squeezing the ebook model into the ejournal model doesn’t quite fit.
It’s easy to set up multiple sales models, but harder to get information about who the customers are and using that to make business decisions.
They’re a little worried that if they give up DRM it will impact print sales, but it’s obviously pretty unpopular and they do want the books to be used. They’re thinking about future formats — EPUB3, HTML5 — they need to keep up. They’re thinking about new ways to sell the content, and increasing the number of platforms and partners they work with.
Speaker: Bob Boissey, Springer
Serials come first at Springer (because they’re 80% of your materials budget). But, he’ll talk about ebooks today.
The STM publisher’s preference is to sell ebooks in packages directly to libraries, but there are other models based on library or patron selection that have some appeal. Eventually, market forces will probably mean they’ll have to do something with PDA.
In the post-PDA world, maybe we stop selecting and make sure that our systems are solid for allowing our users to find the best, most relevant content in an un-scoped collection. Might also mean giving up some of our concepts about what librarianship is.
The easy stuff: Libraries are the traditional purchasers of scholarly books, and publishers know how many print books we’ve purchased from them in the past. Many eresource issues were resolved with ejournals. SERU. The volume discount approach to selling ebook packages can work if the per unit cost is low, the percentage of portfolio used is high, and the spend is commensurate with print spend, but with more titles. Include textbooks and reference books in the package. Remove DRM, pair with liberal use and ILL permissions.
The not so easy, but not so hard stuff: Editors and authors have not had an easy time coming to terms with ebooks, much like print on demand. Discovery layer for ebooks is still the catalog, and it’s not down to the full text quite yet. Tablets are great for ebooks, and as they get more popular on campuses, ebooks get used more. Might have to give up the concept of book as a full thing and be okay with chapter-level reading. Most scholarly books outside of the humanities and social sciences are not read as a whole.